Part 2 of 6 · The Technology Behind Better Outcomes — a technical briefing series from Quill Direct Vet Care.
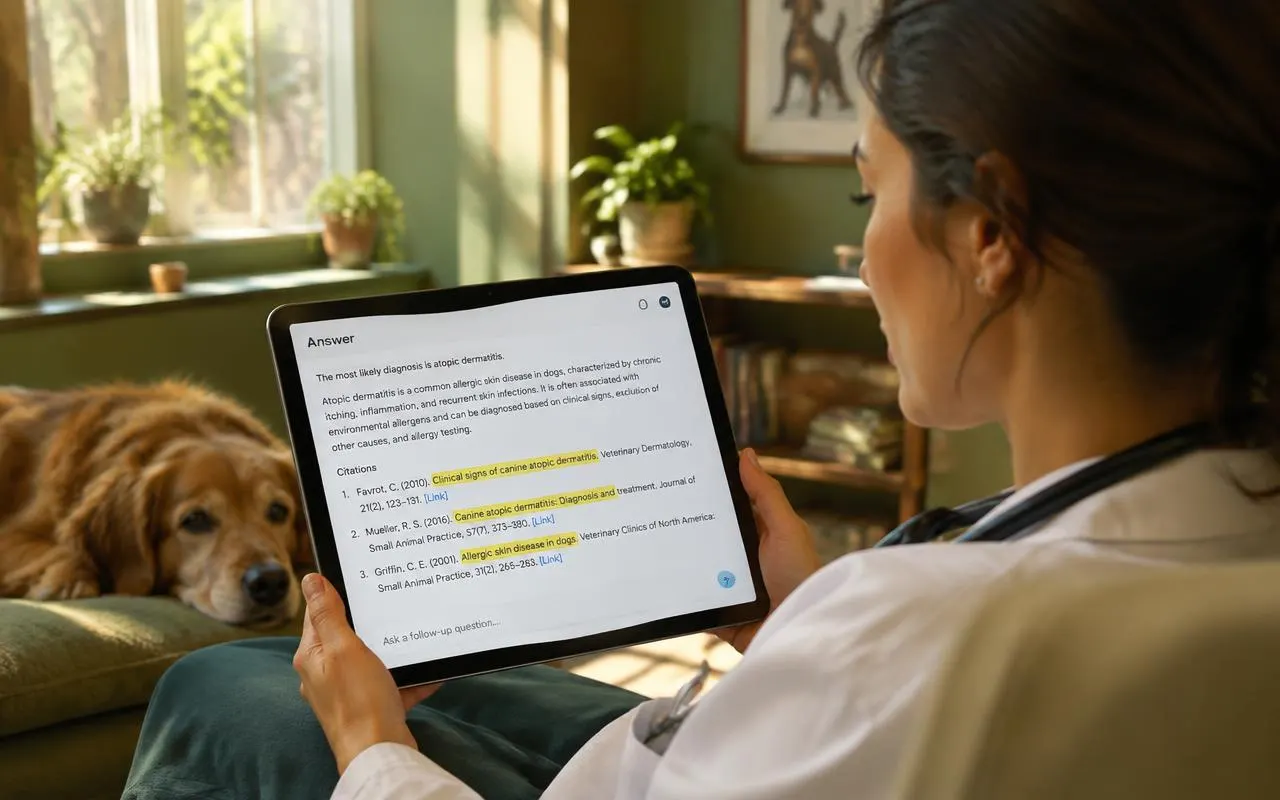
The single most dangerous property of a general-purpose language model in a clinical setting is that it is equally fluent when it is right and when it is wrong. Quill’s clinical AI is built so that fluency is decoupled from authority: an answer is only rendered when retrieved source material supports it, every claim carries a numbered citation back to a document, and the absence of grounding produces a refusal rather than a guess.
1. Why grounding, not fine-tuning
There are two ways to give a model domain knowledge. You can bake it into the weights through fine-tuning, or you can retrieve it at query time and place it in context. Quill chose retrieval, and the reasoning is operational as much as technical.
| Dimension | Fine-tuned model | Retrieval-augmented (Quill’s approach) |
|---|---|---|
| Updating knowledge | Retrain and redeploy; days to weeks. | Re-run the ingestion job; minutes. |
| Attribution | None. The model cannot tell you which document taught it something. | Every sentence maps to a retrieved chunk with a document identifier and URL. |
| Correcting an error | The bad fact is diffused across the weights. | Fix or remove the source document; the error disappears on the next query. |
| Access control | Knowledge is baked in for everyone who can call the model. | Retrieval is filtered per request, so scoping is enforceable. |
| Failure mode | Confident fabrication. | Explicit refusal with an empty citation array. |
The retrieval-augmented generation approach was introduced precisely because grounding generation in retrieved passages produces more specific and more factual output than a parametric model relying on memorized weights. Quill’s implementation adds a hard constraint on top of it: no citation, no answer.
2. How a question becomes a cited answer
Process flow · Illustrative
Embed the query
text-embedding-3-small (1536 dimensions).
Hybrid retrieval
Azure AI Search vet-clinical-v1: vector similarity for meaning, BM25 keyword match for exact drug names, dosages and codes, merged with reciprocal rank fusion.
Filter and rerank
By species, topic, recency and the user's permissions.
Assemble numbered context
Sources [1]…[N], each with document title and URL.
Generate under constraint
gpt-5-mini with a citation-required prompt.
ValidateGuardrail
Every claim must map to a source — otherwise the system refuses.
2.1 Why hybrid retrieval and not pure vector search
Pure semantic search is excellent at concepts and unreliable at tokens. Ask it for content about “kidney problems in older cats” and it performs beautifully. Ask it for a specific compound, a product name, a dosage string, or a claim code and dense embeddings will happily return something adjacent and wrong — because in embedding space, two drug names in the same class sit very close together.
Veterinary medicine is full of exactly those tokens. Quill therefore runs vector and keyword retrieval in parallel and fuses the ranked lists with reciprocal rank fusion, so conceptual recall and literal precision reinforce each other rather than trading off. A semantic reranking pass then reorders the fused set by relevance to the actual question rather than by raw score.
2.2 The schema contract
The retrieval index enforces a strict field contract — document identifier, source, document title, section, species, topics, canonical URL, publication date, content, and content vector. The ingestion pipeline reads the live index schema at startup and drops any field the index does not define before it writes.
That guard exists because of a real production failure. An early ingestion run emitted a title field against an index that defines doc_title, and the service correctly rejected the batch. Rather than patching the one field name, Quill made the pipeline schema-aware so the entire class of mismatch cannot recur. This is the difference between fixing a bug and closing a defect category — and it is the kind of hardening that only comes from operating a pipeline rather than demoing one.
2.3 The citation guardrail
The generation step runs under a versioned system prompt that forbids unsourced assertions. The response contract is machine-checkable:
-
answer — prose in which every substantive claim carries a bracketed numeric citation.
-
citations[] — the resolved source list: document title, section, and canonical URL for each number used.
-
prompt_version — the exact prompt revision that produced the answer, so behavior changes are attributable.
-
retrieval_trace_id — a unique identifier linking the answer to the precise retrieval result set, for audit and evaluation replay.
The refusal is the feature
During validation of the live endpoint, a request for a puppy vaccination schedule was issued against an index containing only a seed document. The system returned a refusal, an empty citations array, and a clarifying question — it did not produce a schedule from model memory.
That is the behavior clinical users need and the behavior a carrier’s risk team wants to see demonstrated. An AI that never says “I don’t know” is an AI that cannot be trusted when it says anything else.
3. Curation is a governance decision, not a scraping job
Retrieval quality is bounded by corpus quality, so Quill treats corpus admission as a controlled process. Content enters the index through a versioned manifest that records provenance, license status, publication date, and review owner for every document. Material without a clean license or a clear provenance chain does not get ingested, regardless of how useful it would be.
Ingestion itself runs as a scheduled, event-driven containerized job that scales to zero between runs — it costs nothing when idle, and each execution emits a log line with the document count written, so a silent partial ingest is detectable. Refresh is a job run, not a deployment.
4. Where grounded answers show up in the product
| Surface | User | What grounding changes |
|---|---|---|
| AI Vet Chat | Pet owner | Guidance is tied to the specific pet’s species, age, breed, and history — and cites the material behind each recommendation instead of producing generic web-tier advice. |
| Symptom triage | Pet owner | Urgency assessment is conservative by construction: when signals are ambiguous, the system escalates to “be seen” rather than reassuring. |
| Diagnostic Encyclopedia | Veterinarian | Presents multiple valid diagnostic approaches with the reasoning behind each, explicitly framed as decision support rather than protocol. |
| Coverage validation | Clinic staff, insurer | Coverage determinations reference the specific policy language relied on, so a denial can be explained to an owner in plain terms. |
| Fraud explanation | Insurer | A flag is accompanied by the pattern and the evidence that produced it, which makes the signal reviewable rather than oracular. |
| Population health | Medical director | Cohort findings link back to the underlying records, so a practice can act on a trend instead of debating whether it is real. |
5. Evaluation as a standing discipline
A grounded system still degrades — an index drifts, a prompt revision regresses, a model upgrade changes refusal calibration. Quill instruments for that:
-
Retrieval quality. Held-out question sets measure whether the correct source appears in the top-k results, tracked per content domain.
-
Citation fidelity. Answers are checked so that every cited number resolves to a retrieved document, and every substantive claim carries one.
-
Refusal calibration. A deliberate set of unanswerable questions verifies the system still declines — over-refusal and under-refusal are both regressions.
-
Latency and cost. Per-feature p95 latency and per-answer token spend are tracked at the gateway, so a quality improvement that quietly triples cost is visible immediately.
-
Replay. Because every answer carries a trace identifier and a prompt version, any historical answer can be reconstructed and re-scored against a new configuration.
6. Why this matters for care
Veterinary practice runs on compressed decision time. A clinician holding a differential at 4:40 p.m. does not need a fluent essay — they need the two or three relevant considerations and a source they can check in fifteen seconds. A pet owner at 11 p.m. deciding whether to drive to an emergency clinic does not need reassurance — they need a conservative, explainable read on urgency.
Citations serve both. They convert the AI from an oracle that must be trusted into an instrument that can be verified, and verification is what makes it safe to use the tool at speed. That is the entire design goal: not to replace veterinary judgment, but to make the evidence supporting a judgment reachable in seconds instead of minutes.
Evidence base
The following peer-reviewed findings were verified against primary sources; full citations appear in the References section.
Ungrounded models fabricate citations at material rates. Across 1,800 references generated from 120 clinical anatomy questions, measured reference-hallucination rates were 23.2% for one frontier model and 45.8% and 47.5% for two others — the failure mode a citation-required architecture is designed to eliminate. (Ülkir & Paslı, Clinical Anatomy, 2026)
Retrieval grounding measurably reduces hallucination. Adding a retrieval-augmented generation framework to four large language models across four medical question-answering benchmarks increased accuracy by 9.8–16.3% (mean 13%) and reduced hallucination rates by 11.8–18% (mean 15.1%). (Wang et al., Journal of Medical Internet Research, 2025)