
✦
AI/ML · 16 min read · September 24, 2026
Engineering the Intelligent Veterinary Operating System
A governed intelligence layer connecting the clinical encounter, documentation, operational decisions, claim quality, payer response, cash, and measured outcomes.
By Quill Direct Vet Care
Executive perspective. Veterinary clinics do not need another disconnected dashboard. They need an operating system for decisions—one that can turn a clinical conversation into structured documentation, convert documentation into a cleaner claim, route exceptions to the right person, reconcile the financial outcome, and learn from every result without hiding the logic from clinicians or operators.
Quill Direct Vet Care is being engineered around that premise. Its differentiator is not a single model or screen. It is the combination of explainable decision engines, governed generative AI, clinic-scoped analytics, workflow automation, and a security architecture designed for sensitive veterinary and financial data. The result is a platform intended to make intelligence operational: embedded where work occurs, traceable to evidence, bounded by policy, and measurable after the decision.
The Quill thesis
The claim is not merely a transaction at the end of care. It is a structured record linking documentation quality, coding, payer requirements, payment timing, clinic performance, and patient outcomes. When that loop is measurable, the clinic can improve the system—not just process the next task.
This article examines the technology behind that thesis, the controls required to make it trustworthy, and why the architecture matters to practice owners, clinical teams, technology leaders, insurers, and investors.
| Capture | Decide | Act | Prove |
|---|---|---|---|
| Turn the encounter into structured, reviewable evidence. | Expose the factors behind risk, confidence, and priority. | Convert signals into bounded, accountable workflows. | Measure outcomes and govern every revision with evidence. |
1. The real problem is fragmentation, not a lack of software
Most clinics already use software. The constraint is that the systems around the exam room, schedule, inventory cabinet, insurance claim, payment, and patient follow-up often behave as separate islands. A note can be clinically adequate but incomplete for reimbursement. A denied claim can be visible to finance but disconnected from the documentation pattern that caused it. A no-show can create an idle room, while replenishment decisions happen without the demand signal contained in scheduled procedures. A population-health list can identify risk without creating an accountable next action.
This fragmentation imposes a compounding operational tax: repeated data entry, manual reconciliation, delayed exceptions, avoidable rework, and management decisions made from backward-looking totals. Quill's architectural response is to treat every consequential workflow as part of a connected evidence chain. A signal becomes a scored decision; the decision becomes a task or controlled action; and the outcome returns to analytics as evidence for the next improvement.
A different category. Quill is best understood as an intelligent veterinary operating layer: it coordinates clinical, operational, claims, payment, and population-health work while preserving the systems of record beneath it.
Why the architecture is competitively different
Many products optimize one moment in the care journey. Quill is designed to optimize the handoffs between moments—the places where evidence is lost, queues grow, and accountability becomes ambiguous. Its competitive advantage is architectural coherence: one governed loop spanning clinical evidence, operational action, financial state, and measured outcome.
| Competitive dimension | Conventional fragmented stack | Quill operating model |
|---|---|---|
| Decision logic | Scores or recommendations may be detached from their rationale. | Factors, weights, thresholds, state transitions, and authorized overrides remain inspectable. |
| Workflow continuity | Clinical, claims, payment, and inventory tools create separate queues. | Signals become bounded actions, and outcomes return to the same measurement loop. |
| AI governance | A model is embedded as a feature and changed by replacement. | Workloads map to approved models through a governed gateway and evidence-based promotion process. |
| Operational proof | Success is inferred from adoption or dashboard activity. | Precision, recall, lift, utilization, exception age, and closure outcomes test whether the workflow improved. |
2. Intelligence begins at the clinical encounter
Ambient documentation that is useful downstream
Quill's AI Scribe workflow is designed around ambient capture, transcription, diarization, and structured SOAP drafting. The important engineering choice is what happens next: documentation completeness can be evaluated before the note becomes the foundation for coding and a claim. Required clinical fields, diagnosis codes, procedure codes, linkage to the encounter, and note finalization become explicit signals rather than assumptions.
That transforms scribing from a convenience into an upstream quality control. Quill does not attempt to replace clinical judgment; it attacks the clerical friction between conversation and structured evidence while keeping the veterinarian responsible for review and finalization. When the visit record is complete at the source, every downstream function—from care continuity to payer review—begins with stronger information.
Clinical intelligence begins in the exam room. The platform is designed to structure the encounter without interrupting the human relationship at its center.
Grounded assistance, with permission to remain silent
The veterinary-assistance pattern is bounded with the same rigor. Pet context and retrieved sources can ground an answer, while triage and safety rules shape the response. The governing principle is “citations or silence”: if the system cannot support a clinical statement with permitted context and sources, it must not manufacture certainty. This is fundamentally different from deploying a general chatbot and hoping a disclaimer will control the risk.
Quill separates model-generated language from deterministic controls. Language models are appropriate for transcription, summarization, structured narration, and grounded assistance. They are not used to conceal the basis of a financial or operational decision. That division of labor is central to trust.
| Generative AI assists language | Deterministic engines control decisions |
|---|---|
| Transcription and SOAP drafting | No-show and slot scoring |
| Grounded veterinary assistance | Policy-gated replenishment |
| Analytics narration | Denial-factor attribution |
| Structured summarization | Claim-state transitions |
Quill assigns generative AI to language-intensive work and deterministic engines to decisions that demand visible rules and accountability. These are architectural classifications, not measured-performance claims.
3. Explainable engines turn data into accountable decisions
Quill's most defensible innovation is not black-box prediction. It is an operating discipline built around transparent engines that expose the factors, weights, thresholds, and actions behind each recommendation. A clinic can inspect the reasoning, correct source data, override where authorized, and measure whether the rule ultimately performed. Intelligence becomes accountable—not merely impressive.
Pre-submission confidence and denial-risk attribution
The claims-confidence engine applies a deterministic scorecard to identify missing or conflicting elements before submission. Its outcome can recommend automatic submission, hold a claim for review, or block an unsafe transition. The denial-risk engine uses an interpretable additive log-odds model. It begins with a payer or portfolio baseline, then reports the signed contribution of documentation, coding, payer history, financial, and process factors. Missing-field impacts are translated into concrete remedies such as expanding exam findings, linking the visit note, or attaching procedure codes.
This distinction is decisive: a risk score without attribution creates another queue; an attributed score creates a repair path. It tells the team not only that a claim is vulnerable, but why—and which action should reduce that vulnerability. The formal claim state machine further constrains movement across draft, validation, visit, processing, approval, payment, settlement, denial, and exception states. Invalid transitions are rejected instead of quietly producing inconsistent records.
Measurement that respects uncertainty
Rules are not treated as permanently correct. Quill's effectiveness layer calculates precision, recall, fire rate, false-positive rate, override rate, and lift against the base denial rate. Wilson score intervals are used so that a two-of-three sample is displayed as uncertain, not promoted as a 67 percent success headline. A minimum sample threshold prevents thin evidence from being mistaken for a durable operational signal.
Why this is difficult to copy. The defensible asset is the feedback loop: documented input → attributed decision → controlled workflow → payer or operational outcome → statistically honest effectiveness measurement → governed rule revision. A feature can be replicated; a continuously measured operating discipline is much harder to reproduce.
4. Analytics that lead to action—not dashboard theater
Quill's analytics engine provides dense time series, period-over-period comparisons, rates, confidence intervals, anomaly scores, trend projection, funnels, and exportable drill-downs. These primitives support clinic-scoped reporting across claims, operations, financial performance, patient populations, and resource use. Importantly, the AI Insight Narrator is designed to receive aggregate metric blocks rather than row-level patient or owner details. The model can prioritize findings and explain movement without requiring identifiable records in the prompt.
Population-health capabilities extend the same approach to cohorts. Clinics can define criteria around species, age, active problems, body-condition score, overdue vaccination, visit recency, environmental exposure, social determinants, and a composite pet-risk score. Cohort membership can be refreshed and snapshotted over time, turning a one-time list into a measurable program. This area remains in active rollout, but the underlying cohort and risk logic demonstrates the platform direction: identify risk, create outreach, enforce consent, and evaluate whether the intervention changed the outcome.
For leaders, the payoff is operational focus. A KPI should open into its contributing records; an anomaly should become an investigation; a threshold breach should create an accountable task; and the result should return to the measurement layer. Quill is designed to close that loop—not to decorate a dashboard.
5. Optimization extends beyond claims
Scheduling intelligence that protects capacity
The scheduling engine scores no-show risk with visible factors, detects provider and room conflicts, recommends slots that reduce idle gaps, and calculates lane utilization by provider or resource. The logic is deterministic and local enough to score many candidate slots without a network round trip. For a clinic, that means recommendations can be fast, explainable, and aligned to operational constraints rather than generated from an opaque model.
Inventory intelligence with policy-gated autonomy
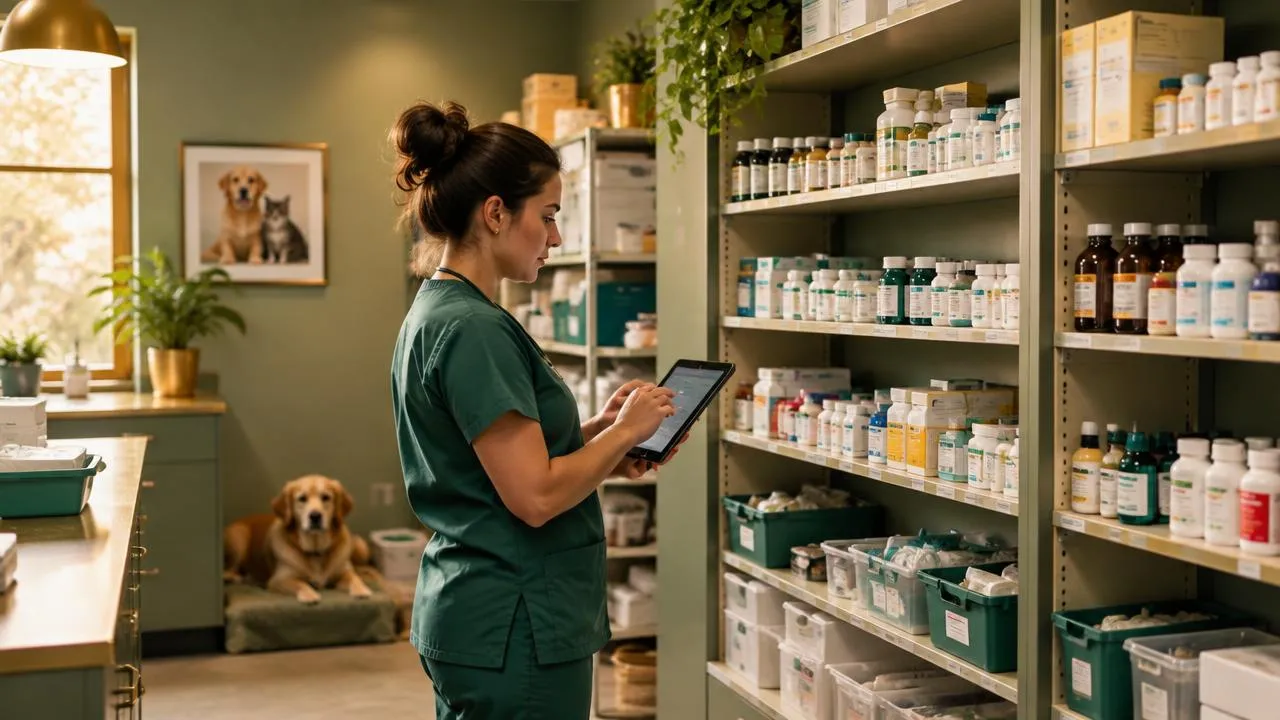
Inventory workflows combine forecasting, reorder signals, vendor quotes, receiving, lot tracking, expiration-first controls, and anomaly detection. The replenishment assistant has a separate policy gate for quote, award, order, and payment steps. It evaluates approved vendors and categories, controlled-drug exclusions, per-order and monthly caps, price drift, blocked items, and whether Quill-managed payment has been authorized. A step outside policy is denied with a reason and routed for human approval.
This is responsible automation made concrete. The system does not receive a vague instruction to “optimize inventory.” It receives a narrow authority boundary, applies it consistently, records why an action was allowed or blocked, and routes controlled or exceptional cases to a person. Automation earns trust by staying inside its mandate.
Payments and exception resilience
Claims and payment workflows are modeled as stateful processes rather than fire-and-forget messages. Payment timelines, payout reconciliation, retry policies, and exception handling provide the foundation for tracing a transaction from approval through settlement. This architecture supports operational recovery: a failed event can be retried or moved into an exception path instead of disappearing between systems. Any production financial workflow still requires deployment-specific controls, reconciliation testing, and partner validation, but the application's design reflects those realities.
6. Interoperability is an architecture, not a checkbox
Quill's insurer exchange design recognizes that veterinary and insurance ecosystems do not speak one protocol. The platform models REST APIs, EDI X12, FHIR, HL7, SFTP, code crosswalks, field mappings, transmission tracking, and HMAC-signed webhooks. This is the correct abstraction for a platform that must connect modern APIs and legacy transaction channels without forcing clinics to understand the transport.
The distinction between designed capability and live connectivity is essential. Quill currently provides the application structures and workflows for these exchanges; production clearinghouse and payer connectivity remains partner- and implementation-dependent. Standards such as FHIR and X12 provide important exchange foundations, but implementation still requires governed mappings, transport controls, and partner validation.7 8 Stating that boundary clearly is a mark of technical credibility.
7. The governed intelligence loop
The following sequence summarizes how Quill is designed to move from a clinical or operational event to an auditable outcome. Generative AI is one participant in the loop—not the control plane.
| 1 Capture | 2 Structure | 3 Decide | 4 Act | 5 Learn |
|---|---|---|---|---|
| Encounter, schedule, claim, payment, inventory, and environmental signals | SOAP note, codes, normalized events, patient facts, and transaction states | Rules, attributed risk, thresholds, forecasts, and governed AI assistance | Submit, hold, route, reconcile, schedule, replenish, or contact—with policy gates | Outcomes, precision and recall, anomalies, utilization, cost, and quality feedback |
Every automated action is intended to remain attributable to data, rule, model version, policy, and user authority.
8. Azure security and AI governance: separating runtime from control
Quill's Azure direction is designed around separation of duties. Azure API Management provides a stable gateway so application features are not coupled to a specific model endpoint.3 Managed identity authenticates the gateway to Azure AI services,2 while Key Vault holds feature-specific credentials and application configuration maps each workload to an approved deployment. Per-feature products allow rate limits, quotas, telemetry, and cost attribution to be applied independently. Request and response bodies are excluded from gateway diagnostics because clinical content may be sensitive; operational metadata and correlation identifiers support end-to-end tracing. Microsoft's published Azure OpenAI data-privacy guidance informs these workload boundaries.1
Private endpoints, segmented networks, centralized identity through Microsoft Entra ID, least-privilege roles, firewall defaults, and controlled administrative access form the surrounding security pattern.5 Data residency and minimization are workload-level decisions: veterinary chat and scribe content have different exposure boundaries than an analytics narrator that receives only aggregates. The architecture also separates development and production and treats model capacity, latency, fallback behavior, and cost ceilings as production controls rather than afterthoughts.
Model choice becomes an evidence problem
The Azure AI Foundry layer answers a critical question: which model should power each feature, and on what evidence? Quill's runbook defines de-identified golden datasets by workload, built-in and deterministic evaluators, comparison runs across candidate deployments, online sampling, and promotion gates.4 Scribe evaluation emphasizes groundedness, similarity, and required-field coverage; analytics narration adds structured-output and metric-identifier validity; denial-support language adds a “no invented clinical claim” grader.
Every model-map change is intended to carry an evaluation-run identifier, quality scores, latency, cost, approver, and rollback point. The design explicitly rejects promotion merely because a model is newer. A quality gain that triples cost or breaches a workflow latency target may be the wrong operational choice. Models are replaceable components; evaluation evidence and governance are durable platform capabilities.
9. Security is a system of evidence
Veterinary platforms handle a consequential mix of clinical narratives, owner contact information, insurance records, payment data, credentials, and operational telemetry. Quill's security requirements therefore span governance, data classification, identity, API controls, encryption, network segmentation, vendor due diligence, incident response, and auditable claims data flows. The application includes masking and log-redaction helpers, event logging, role-sensitive navigation, and tenant-scoped data access patterns.
Architecture alone is not certification. Quill's compliance views and requirement registers are internal control documentation unless and until a control is independently tested or attested. That distinction strengthens the security culture: controls must produce evidence—configuration records, logs, access reviews, test results, restore exercises, and remediation history. The target posture aligns with zero-trust principles: never grant trust from network location alone; authenticate explicitly; authorize narrowly; and assume every boundary will eventually be tested.6
For clinics and partners, this translates to practical questions the platform is designed to answer: Who accessed a sensitive record? Which tenant and role authorized the action? Which rule or model version influenced the recommendation? What data crossed an integration boundary? Was the payload minimized? Can the organization reconstruct the event without storing clinical bodies in infrastructure logs?
10. What this means for veterinary clinics
| Clinic priority | How Quill addresses it |
|---|---|
| Protect clinician time | Ambient documentation and structured completeness checks reduce avoidable re-entry while preserving veterinarian review. |
| Prevent revenue rework | Attributed confidence and denial-risk factors expose correctable documentation, coding, and process gaps before submission. |
| Use capacity better | Explainable no-show risk, conflict detection, slot recommendations, and room/provider utilization support tighter schedules. |
| Control supply cost | Forecasting, quote comparison, FEFO and lot controls, and policy-gated replenishment focus automation within approved limits. |
| Act on population risk | Editable cohorts connect clinical, environmental, social, and utilization signals to measurable outreach programs. |
| Make decisions defensible | Audit events, formal state transitions, confidence intervals, model evaluation, and role boundaries create traceable evidence. |
| Integrate without rebuilding | A protocol-aware exchange layer is designed to isolate clinic workflows from payer and partner transport differences. |
Quill's economic promise is therefore not a speculative percentage. It is a set of measurable levers: documentation completion, preventable defect volume, days to outcome, exception age, schedule utilization, stockout exposure, price variance, manual touches, and task closure. Clinics can establish a baseline, deploy a workflow, and measure whether the operating result improved.
11. A platform thesis built for the next veterinary decade
The next generation of veterinary technology will not be defined by the number of AI buttons in a user interface. It will be defined by whether intelligence can operate safely across the full workflow: grounded in evidence, explainable to the people accountable for the decision, isolated to the correct organization, constrained by policy, observable under load, and connected to an outcome that matters.
Quill Direct Vet Care is building toward that standard. Its strongest idea is architectural: connect the encounter to the claim, the claim to cash, operations to capacity, population signals to action, and every recommendation to evidence. Use generative AI where language is the problem. Use deterministic engines where accountability is the problem. Use analytics to test whether either one worked. Use Azure security and evaluation controls to make model choice governable rather than fashionable.
For clinics, this means technology engineered to return time, expose preventable work, protect scarce capacity, and make clinical and financial operations legible. For partners and investors, it means a platform whose defensibility compounds with the quality of its measured loops—not merely the length of its feature list. Quill's ambition is demanding but clear: make every consequential workflow more intelligent, every automated decision more governable, and every outcome more measurable.
Current capability. Available application capabilities described in this article include the explainable rules and denial-risk engines, claim lifecycle controls, analytics primitives, clinic-scoped reporting surfaces, scheduling logic, inventory policy gates, cohort logic, audit utilities, and AI-enabled workflows present in the Quill application. Security requirements and dashboards are internal control artifacts, not a statement of third-party certification. Product capabilities, availability, and controls may change as deployment validation progresses.
About Quill Direct Vet Care
Quill Direct Vet Care is developing an intelligent operating platform for veterinary care. Quill connects clinical documentation, claims integrity, payments, scheduling, inventory, population health, analytics, and governed AI so clinics can replace fragmented handoffs with accountable, measurable workflows. The platform is designed to help veterinary teams protect clinical time, strengthen operational and financial visibility, and act on evidence without surrendering professional judgment or governance.
References
- Microsoft: Data, Privacy, and Security for Azure OpenAI Service (accessed September 17, 2026).
- Microsoft: Authenticate and Authorize to Azure OpenAI (accessed September 17, 2026).
- Microsoft: Import an Azure OpenAI API into Azure API Management (accessed September 17, 2026).
- Microsoft: Evaluate Generative AI Applications (accessed September 17, 2026).
- Microsoft: Configure a Private Link for Azure AI Foundry (accessed September 17, 2026).
- National Institute of Standards and Technology: Zero Trust Architecture (accessed September 17, 2026).
- HL7 International: FHIR Overview (accessed September 17, 2026).
- X12: Insurance (accessed September 17, 2026).
Keep reading
Technical Briefings · 44 min read
How veterinary AI can reduce claim denials
How AI can review a veterinary insurance claim before it is filed, cite its sources and leave every decision with the clinician.
Innovation · 13 min read
Why veterinary PIMS integrations stop short of a paid claim
Most veterinary PIMS integrations move data. A claim is only finished when it is paid. Here is how QuillsFlow is designed to close that loop.